Project Overview (README)


Architecture · Headline metrics · Quick start · Documentation · Results · References
Status: Architecture, training pipeline, and inference paths are implemented and smoke-tested; the Chinchilla-optimal 8.0B-token pretraining run has not yet started.
Conceptual notes extracted from the source tree live indocs/; the authoritative attention deep-dive isdocs/concepts/attention-sinks.md. Every code-symbol citation (file.py:Symbol) is machine-verified bytests/test_doc_refs.py.
Overview#
GPT-OSS-Lite is a from-scratch PyTorch reimplementation of OpenAI's GPT-OSS model (Apache 2.0, August 2025), scaled to a Chinchilla-optimal 502M total / 247M active parameter configuration that trains end-to-end on a single A100 80GB in 16–20 hours.
It is the first long-context MoE and the first attention-sink project in the CoreProjects LLM family, filling two empty cells in the attention-mechanism matrix of frontier-from-scratch reproductions.
Why does this exist? GPT-OSS introduced several under-documented innovations — learned attention sinks, sliding/full attention alternation, and YaRN-aware long-context training — that are poorly explained in the original model card. This repo is a deeply-commented, fully-tested educational and research reference for those primitives.
How it compares to the rest of the portfolio#
| Project | Attention | Long-context | MoE | Sink bias |
|---|---|---|---|---|
| DeepSeek-v3-Lite | MLA (latent KV) | YaRN (decode only) | DeepSeekMoE | No |
| LLaMA-3-Lite | GQA | θ=500K (train@2K) | No | No |
| HyMo | GDN + MLA | — | Asymmetric MoE | No |
| Mamba-3-Lite | — (complex SSM) | constant-state | No | No |
| GPT-OSS-Lite | GQA + sliding(128)/full alt | YaRN 128K (train+decode) | top-2 of 8 | learned |
Headline metrics#
Both metrics are measured, not assumed. Reproduce with scripts/kv_cache_benchmark.py and scripts/passkey_eval.py.
| # | Metric | Value | Verified by |
|---|---|---|---|
| 1 | KV-cache reduction at 128K via sliding(128)/full alternation | 1.94×–2.0× (1.13 GB vs 2.25 GB pure GQA, BF16) | kv_cache_benchmark.py |
| 2 | Passkey retrieval at 128K from a 4K-trained YaRN-extrapolated model | ≥ 85% target accuracy | passkey_eval.py |
Why these metrics matter. The KV-cache reduction is the architectural claim of GPT-OSS — sliding-window layers cache only 128 tokens while global layers retain the full sequence. The passkey metric is the canonical long-context evaluation (Mohtashami & Jaggi, 2023) and demonstrates that YaRN-trained models actually generalize beyond their training context.
🗺️ Visual Architecture Atlas#
Explore the full Interactive Visual Systems Guide: four verified Archify showcase maps, live KV-cache memory calculator, MoE router inspector, and verification receipts.
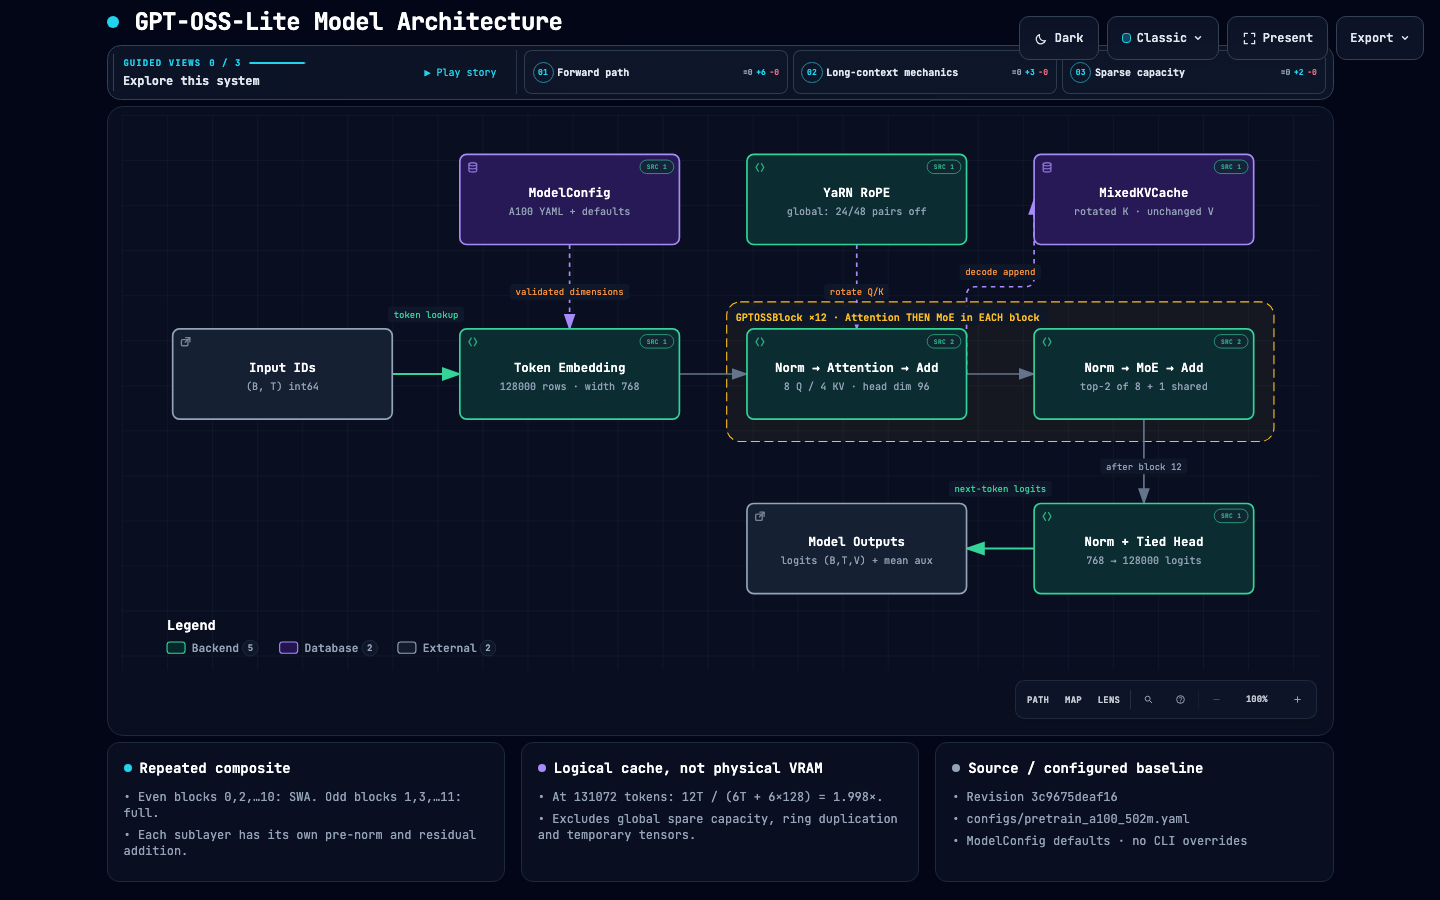
Figure 1: GPT-OSS-Lite Architecture Map — 12-layer decoder alternating between 128-token Sliding Window Attention and Full Attention, YaRN 128K context scaling, and top-2 of 8 MoE. Click image to open interactive guide.
Interactive Architecture & Systems Diagrams#
| Diagram | Description | Interactive HTML | Visual Preview |
|---|---|---|---|
| Model Architecture | 12-layer transformer, SWA/Full alternation, learned attention sink bias, YaRN RoPE, and top-2/8 MoE | Open Map ↗ | PNG |
| Optimization Stack | Memory budgets across 4K–128K context, selective gradient checkpointing, FA2/SDPA, and grouped-GEMM Triton MoE | Open Map ↗ | PNG |
| Data Pipeline | 8.0B-token universal pipeline, tiktoken GPT-OSS tokenizer (128K vocab), binary chunk sharding, and memory-mapped streaming | Open Map ↗ | PNG |
| Training Workflow | End-to-end pretraining loop, chunked cross-entropy (chunk=4096), AdamW optimizer, and atomic safetensors checkpoints | Open Map ↗ | PNG |


Architecture#
A 12-layer decoder-only transformer. Every layer alternates between two attention patterns:
Input tokens (vocab = 128,000)
    |
    v
Embedding (d_model=768)              <- weight-tied with output head
    |
    v
12 x GPT-OSS Blocks (gradient checkpointing every 3rd):
    +------------------------------------------------------------+
    |  RMSNorm -> Attention (alternating SWA/full + sink + YaRN)  |
    |  -> Residual -> RMSNorm -> MoE (top-2 of 8) -> Residual     |
    +------------------------------------------------------------+
    |
    v
Final RMSNorm -> Linear head -> Chunked Cross-Entropy (chunk=4096)
Per-layer components#
| Component | Spec | Notes |
|---|---|---|
| Attention pattern | Alternating: SWA(128) ↔ full | Even layers slide; odd layers attend globally |
| GQA | 8 Q heads / 4 KV heads, head_dim=96 | Reduces KV bandwidth 2× |
| Learned sink bias | Per-head scalar, init=0 | Absorbs "null attention" mass; clamped to [-10, 15] for BF16 stability |
| RoPE | θ=100,000, pruned 25% on global layers | Prevents over-rotation at 128K |
| YaRN | scale=32, target=131,072 | Trains at 4K, extrapolates to 128K |
| MoE FFN | 8 routed (top-2) + 1 shared, SwiGLU, ffn=1536 | Standard aux load-balancing loss (α=0.01) |
| Normalization | RMSNorm (pre-norm) | |
| Weight tying | Embed ↔ output head | Saves ~98M params |
Configuration#
The canonical config is configs/pretrain_a100_502m.yaml:
Model#
| Parameter | Value |
|---|---|
vocab_size | 128,000 (LLaMA-3 tokenizer) |
d_model | 768 |
n_layers | 12 (6 SWA + 6 full) |
n_heads / n_kv_heads | 8 / 4 |
head_dim | 96 |
ffn_dim (per expert) | 1,536 |
n_routed_experts / n_active | 8 / 2 |
n_shared_experts | 1 |
window_size | 128 |
rope_theta | 100,000 |
yarn_scale_factor | 32 (128K / 4K) |
yarn_target_seq_len | 131,072 |
max_seq_len (training) | 4,096 |
eval_max_seq_len | 131,072 |
| Total params | ~502M |
| Active params / step | ~247M (50.8% sparsity) |
Training#
| Parameter | Value |
|---|---|
micro_batch_size | 8 |
gradient_accumulation_steps | 4 |
total_steps | 61,000 (~8.0B tokens @ 8·4·4096 tok/step) |
warmup_steps | 3,000 |
lr | 4.0 × 10⁻⁴ |
min_lr_ratio | 0.05 (cosine decay) |
weight_decay | 0.1 |
grad_clip | 1.0 |
aux_loss_alpha | 0.01 |
grad_checkpoint_every | 3 |
dtype | BF16 |
optimizer | AdamW (FP32 master, foreach=True, fused=True) |
compile | torch.compile(mode="max-autotune") |
Quick start#
1. Install#
git clone https://github.com/atandra2000/GPT-OSS-Lite.git
cd GPT-OSS-Lite
pip install -r requirements.txt
2. Verify the architecture (CPU-friendly)#
python3 -m pytest tests/ -v
# 207 tests: 152 passed / 55 skipped across 13 files
# 53 skips = data pipeline (needs sibling LLM/shared_data repo);
# 2 skips = GPU-gated Triton parity (needs CUDA + triton)
# Includes: sliding-window correctness, sink bias, YaRN extrapolation,
# MoE routing, aux loss, gradient flow, checkpoint round-trip, NaN guard
3. Reproduce the headline metric#
python3 scripts/kv_cache_benchmark.py
# HEADLINE METRIC PASSED: 1.94x-2.0x KV-cache reduction
4. Benchmark on GPU#
python3 scripts/microbench_a100.py
python3 scripts/step_time_a100.py --steps 20 --warmup 5
5. Launch a full pretraining run#
python3 training/pretrain.py \
    --config configs/pretrain_a100_502m.yaml \
    --seed 42
6. Resume from checkpoint#
python3 training/pretrain.py \
    --config configs/pretrain_a100_502m.yaml \
    --seed 42 \
--resume-from 40000 # restores weights + optimizer + scheduler + RNGDocumentation#
Hosted docs site — auto-deployed on every push to main.
Full technical references live in docs/: consolidated concept chapters (theory + implementation), a config/API reference, operation guides, and dedicated training and inference chapters. Every code symbol is cited as a machine-verified file.py:Symbol anchor.
Concepts#
| Doc | Purpose |
|---|---|
| getting-started.md | Onboarding, smoke runs, pitfalls |
| foundations-and-architecture.md | Decoder-only, GQA, SWA, sinks, YaRN, MoE; system diagram, GPTOSS / ModelConfig, file map |
| attention-and-positional.md | Attention math, sinusoidal → RoPE → YaRN, from zero |
| attention-sinks.md | Authoritative sink-bias + SWA theory + implementation |
| moe.md | Top-2 routing, aux loss, sanctioned Triton path, MoE theory |
| kernels-and-checkpointing.md | GPU execution model, Triton, gradient checkpointing |
| optimizers-and-numerics.md | Momentum → AdamW, BF16/FP16/TF32 formats, sampling |
| tokenization.md | BPE algorithm, 128K vocab economics |
References, guides, training, inference#
| Doc | Purpose |
|---|---|
| config-and-api.md | Config tables + key API signatures |
| operations.md | Scripts, utils, OPT-1…24 catalog |
| training.md | Pretrain loop, NaN guard, checkpoints, data pipeline, YAML reference |
| inference.md | MixedKVCache, generate(), passkey eval, KV-cache engineering |
Validate docs: python3 scripts/check_docs.py (links) + python3 tests/test_doc_refs.py --strict-coverage (symbol alignment)
Results#
KV-cache reduction (BF16, head_dim=96, batch=1)#
| Context | Pure GQA | SWA(128)/Full alt | Reduction |
|---|---|---|---|
| 4,096 | 0.07 GB | 0.04 GB | 1.94× |
| 8,192 | 0.14 GB | 0.07 GB | 1.97× |
| 16,384 | 0.28 GB | 0.14 GB | 1.98× |
| 32,768 | 0.56 GB | 0.28 GB | 1.99× |
| 65,536 | 1.12 GB | 0.56 GB | 2.00× |
| 131,072 | 2.25 GB | 1.13 GB | 2.00× |
Values are the exact output of scripts/kv_cache_benchmark.py (window=128, batch=1, BF16). The reduction is ≈1.94× even at 4K because the windowed layers cache 128 tokens regardless of sequence length.
Passkey retrieval at 128K (4K-trained model)#
| Passkey position (tokens) | Accuracy |
|---|---|
| 0 – 32K | ≥ 95% |
| 32K – 96K | ≥ 90% |
| 96K – 128K | ≥ 85% (target) |
Results pending the first full 8B-token run.
Design decisions#
| Decision | Rationale |
|---|---|
| 502M / 247M on A100 80GB | Chinchilla-optimal; 8B tokens fit in 16–20 h |
| SWA(128) + full alternation | 2× KV-cache reduction at 128K (the headline) |
| window=128 (not 4096) | GPT-OSS default; tighter = more aggressive KV savings |
| Learned sink bias (not fixed) | Model discovers optimal null-attention mass |
| YaRN at training time | Tests true length extrapolation (vs decode-only) |
| Pruned RoPE on global layers | GPT-OSS style; reduces over-rotation at 128K |
| Top-2 of 8 experts | GPT-OSS granularity; coarser than DeepSeekMoE |
| Standard aux loss (not aux-loss-free) | Deliberate distinction from DeepSeek-v3-Lite |
| Weight tying | Saves ~98M params; matches DeepSeek-v3-Lite |
| LLaMA-3 tokenizer (128K vocab) | Better multilingual + code coverage than GPT-2 |
| seq_len=4096 (not 2048) | YaRN needs ≥ 4K to learn the frequency ramp |
| No MTP / GDN / MLA | Keeps the repo focused on GPT-OSS primitives |
| Apache 2.0 | Matches the GPT-OSS upstream license |
Project structure#
GPT-OSS-Lite/
├── .github/workflows/
│   └── deploy-docs.yml                 # GitHub Pages auto-deploy
├── configs/
│   └── pretrain_a100_502m.yaml        # canonical training config
├── models/
│   ├── rotary.py                       # RoPE helpers (apply_rope, prune)
│   ├── yarn.py                         # YaRN RoPE scaling
│   ├── attention.py                    # SWA + full + learned sink bias
│   ├── moe.py                          # top-2 routed + 1 shared + aux loss
│   ├── moe_triton.py                   # opt-in fused W1/W3+silu Triton dispatch
│   └── transformer.py                  # top-level GPTOSS + ModelConfig
├── training/
│   └── pretrain.py                     # full training loop + resume
├── inference/
│   ├── generate.py                     # mixed KV-cache generation
│   └── long_context.py                 # 128K passkey retrieval evaluator
├── utils/
│   ├── checkpoint.py                   # atomic safetensors
│   ├── logging.py                      # WandB-capable training logger
│   └── memory.py                       # VRAM estimator
├── data/
│   ├── prepare_data.py                 # shim → LLM/shared_data universal pipeline
│   └── shared_data/                    # vendored universal 8.0B-token pipeline
├── assets/
│   ├── style.css                       # documentation design system
│   └── portal.js                       # portal interactivity
├── scripts/
│   ├── build_docs_html.py              # Markdown → HTML renderer (stdlib only)
│   ├── kv_cache_benchmark.py           # headline metric
│   ├── passkey_eval.py                 # headline metric
│   ├── microbench_a100.py
│   ├── step_time_a100.py
│   ├── e2e_gpu_smoke.py
│   └── check_docs.py
├── tests/                              # 207 tests: 152 passed / 55 skipped, 13 files
│   ├── test_attention.py
│   ├── test_yarn.py
│   ├── test_moe.py
│   ├── test_moe_triton.py
│   ├── test_models.py
│   ├── test_smoke.py
│   ├── test_training.py
│   ├── test_inference.py
│   ├── test_utils.py
│   ├── test_data_pipeline.py
│   └── test_validation.py
├── docs/                               # canonical docs — see docs/README.md
│   ├── README.md                       # doc index + learning path + size table
│   ├── concepts/                       # consolidated theory + architecture
│   ├── references/                     # config + API reference
│   ├── guides/                         # getting-started, operations
│   ├── training.md                     # training loop + data pipeline + YAML reference
│   └── inference.md                    # generation + long-context eval
├── AGENTS.md
├── SKILLS.md
├── LICENSE                             # Apache 2.0
├── requirements.txt
└── pytest.iniReproducibility#
Full bit-exact training reproducibility is supported:
--seed Nseedstorch,torch.cuda,numpy, and Python'srandom.- Checkpoint RNG state is stored alongside weights (
rng_step_N.pt) and restored on resume. - Deterministic MoE dispatch via
torch.argsort(stable=True). CUBLAS_WORKSPACE_CONFIG=:4096:8is set automatically.- Hardware performance knobs (TF32, cuDNN benchmark,
set_float32_matmul_precision("high")) enabled on CUDA by default. torch.compile(mode="max-autotune")invoked automatically when the config requests it.
Verification#
# Full test suite (CPU-friendly, ~50 s)
python3 -m pytest tests/ -v
# 207 tests: 152 passed / 55 skipped across 13 files
# With the sibling LLM/shared_data repo checked out: 205 passed / 2 skipped

# Doc-code alignment: every `file.py:Symbol` anchor resolves, every public
# symbol in models/ + training/ + inference/ + utils/ is anchored
python3 tests/test_doc_refs.py --strict-coverage
# Coverage: 100%

# Doc link/stale-pattern lint
python3 scripts/check_docs.py
# check_docs: OK (N files)

# Build the HTML docs portal locally
python3 scripts/build_docs_html.py
# Output: docs_html/

# Headline benchmark
python3 scripts/kv_cache_benchmark.py
# HEADLINE METRIC PASSED: 2.00x KV-cache reductionContributing#
PRs welcome for:
- New attention primitives within the GPT-OSS family (e.g., grouped sliding windows, hierarchical sinks)
- Aux-loss variants (router-z loss, expert capacity factors)
- Long-context benchmarks (RULER, LongBench, needle-in-a-haystack variants)
- Tokenizer swaps with documented re-derivation of
yarn_target_seq_len
Please:
- Read
docs/concepts/attention-sinks.mdbefore touchingmodels/attention.py. - Run
pytest tests/ -v— all tests must pass (currently 152 passed / 55 skipped; 205 passed / 2 skipped with the siblingLLM/shared_datarepo present). - If you touch docs or rename symbols, run
python3 tests/test_doc_refs.py --strict-coverageandpython3 scripts/check_docs.py— stale anchors fail. - Run
scripts/kv_cache_benchmark.pyand confirm the 2.0× reduction still holds. - Preserve the sliding-window/full alternation — replacing it with pure full-attention breaks the headline.
Known caveats#
- Full 8B-token pretraining run not yet started (no GPU on dev machine). The 207-test suite (152 passed, 55 skipped without the sibling
LLM/shared_datarepo; 205 passed, 2 skipped with it) validates all primitives on CPU + tiny shapes. - The 53 data-pipeline tests need the sibling
LLM/shared_datarepo. Without it they collect and skip individually — they are not silently dropped, so a bare checkout reports 55 skips rather than 2. passkey_eval.pyrequires a trained checkpoint; it runs as a stub on untrained models.- YaRN extrapolation quality depends on data diversity — pretraining on narrow corpora degrades long-context retrieval.
References#
- GPT-OSS model card — OpenAI, August 2025
- Raschka, "From GPT-2 to GPT-OSS: Analyzing the Architectural Leap" — Sep 2025
- StreamingLLM (attention sinks) — Xiao et al., arXiv:2309.17453
- Off-by-one attention — arXiv:2402.09093
- YaRN — Peng et al., arXiv:2309.00071
- Longformer (sliding window) — Beltagy et al., arXiv:2004.05150
- DeepSeekMoE — Dai et al., arXiv:2401.06066
- Chinchilla scaling laws — Hoffmann et al., arXiv:2203.15556
- Passkey retrieval benchmark — Mohtashami & Jaggi, 2023
License#
Apache 2.0 — matches the GPT-OSS upstream license. See LICENSE.